
What Database Documentation Should Include to Prevent Costly Errors
Database documentation is often treated as a checkbox exercise, yet the costs of neglecting it accumulate faster than teams expect. According to Actian (2026), poor data quality costs organizations an average of $15 million per year through errors, slow onboarding, and compliance failures. The real gap is not a lack of awareness – it is a lack of structure. Teams that build living documentation covering schemas, data dictionaries, ERDs, and governance rules – and keep it synchronized with every schema change – operate with a speed and confidence that static, manual approaches simply cannot match.
This article explains what separates database documentation that gets used from documentation that gathers dust, and why treating it as a business asset rather than a technical chore cuts onboarding time, audit prep, and the hours lost tracing undocumented relationships.
Table of contents
- Why Does Poor Database Documentation Cost More Than You Think?
- Core Components Every Database Documentation Needs
- Best Practices for Building Sustainable Database Documentation
- How Do You Prevent Schema Drift and Keep Documentation Living?
- Database Documentation and Compliance: Does ISO 27001 Require It?
- Tools and Approaches: Are Spreadsheets Enough for Database Documentation?
- Getting Started: Your Database Documentation Roadmap
- Frequently Asked Questions
Why Does Poor Database Documentation Cost More Than You Think?
Database documentation debt accumulates like financial debt: slowly at first, then suddenly. The visible costs are clear – a developer spends hours tracing undocumented foreign key relationships, a new hire takes weeks to understand a schema that should take days. The invisible costs are worse. According to Invensis (2026), citing Wakefield Research, over half of organizations report that data quality issues affect 25% or more of their revenue through flawed analytics, compliance penalties, and wasted engineering time.
The hidden price of manual documentation
A column named usr_flg_3 with no description becomes a gamble every time it appears in a query. A stored procedure without documented inputs becomes untouchable by anyone who did not write it. A table holding customer PII without any classification record becomes a compliance liability waiting to surface at the worst moment. Each gap is individually small. Aggregated across an organization’s full database estate, they produce the multi-million-dollar annual figures consistently cited in enterprise data quality research.
Documentation debt and technical compounding
Every undocumented schema change multiplies inconsistency. Six months after an undocumented column modification, three developers hold three different mental models of what that field means. Decisions made on those diverging assumptions produce cascading errors that are expensive to trace and expensive to explain to auditors. The practical result: teams slow down, onboarding stretches from days into weeks, and every data consumer – engineers, analysts, product managers – works with reduced confidence in the numbers they rely on.
Core Components Every Database Documentation Needs
Complete database documentation is not a single document. It is a structured set of artifacts that together answer every question any data consumer might have about your database.
Schema and DDL scripts form the foundation. These capture the physical structure of every table, view, and index: column names, data types, constraints, defaults, and the CREATE statements needed to recreate the schema from scratch. Without them, disaster recovery becomes guesswork.
Data dictionaries add business meaning to technical fields. What does cust_type_cd mean? What values are valid? Who owns it? When this metadata is accessible to every team member – not just the DBA who designed the table – data literacy scales with the organization rather than bottlenecking on a few individuals.
Raw DDL hides structural patterns that only become visible once you draw them. Entity-Relationship Diagrams (ERDs) translate the schema into a visual map showing cardinality and foreign key paths. For teams who need their ERDs to stay current automatically, interactive schema visualization generates diagrams directly from live schema imports, closing the gap between diagram and database reality.
SQL procedures, triggers, and stored logic are the most frequently underdocumented part of any production database. Every procedure should have documented inputs, outputs, and side effects. A trigger that silently updates an audit table is not visible from the schema alone.
User guides for different personas complete the picture. Engineers need technical depth; analysts need field-level business definitions; support teams need to know where to find specific records. Documentation that serves only one audience fails all the others.
Best Practices for Building Sustainable Database Documentation
Sustainable documentation is documentation that stays accurate over time. That requires embedded process, not just good intentions.
Establish naming conventions and standardized formats from the start. DatastackHub (2026) confirms that data standardization improves data quality, enables seamless integration, supports compliance, and reduces manual cleaning efforts across organizations. A consistent naming convention – whether snake_case, prefixed table types, or standardized abbreviations – means documentation written by one team member is interpretable by the next without translation.
Document normalization decisions and design rationale. When a table is deliberately denormalized for performance, or a foreign key is intentionally absent to support a specific query pattern, that decision should live alongside the schema. The rationale is as valuable as the structure itself. Without it, the next developer may “fix” a deliberate choice and introduce a regression that takes days to diagnose.
Create and maintain ERDs with relationship cardinality. An ERD last updated eighteen months ago is worse than no ERD – it creates false confidence. Treat ERD generation as an automatic output of schema changes, not a separate project with its own timeline.
Assign ownership and governance rules. Every table and every sensitive field should have a named owner responsible for keeping its documentation accurate. Governance without clear ownership is policy without enforcement.
Build documentation as part of schema deployment, not after. The right moment to document a new column is when it is created – the developer who created it holds the context. For teams looking to make this repeatable, the practical guide to database documentation covers how to embed documentation into deployment workflows so it is never an afterthought.
How Do You Prevent Schema Drift and Keep Documentation Living?
Schema drift – the growing divergence between a live database and its documentation – is the primary failure mode in database documentation programs. It is not caused by bad intentions; it is caused by architecture. When documentation lives in a separate system from the schema, every change creates an opportunity for the two to diverge.
Why static documentation fails
Static documentation has a structural flaw: it has no awareness of the database it describes. A column can be dropped, a foreign key constraint removed, a stored procedure rewritten – and the document will never know. In any active codebase, this gap opens within weeks. Teams stop trusting the documentation. They stop updating it. The investment is lost.
Synchronizing documentation with actual database changes
The answer is tighter coupling between the schema and its documentation layer. When a schema is re-imported, the documentation platform should reconcile the new structure against the existing record, surfacing what changed and prompting updates where needed. Automatic schema import addresses this at the source: schema changes are reflected immediately, with change signals that prompt the relevant team members to update field-level context.
Automating documentation updates at deployment time
The most durable approach ties documentation updates to deployment pipelines. A schema migration that ships without a corresponding documentation update becomes a defined blocker, not an optional follow-up. Collaborative documentation workflows make this practical for distributed teams – the team member closest to a change can update its context in real time, at the moment the change is deployed.
Database Documentation and Compliance: Does ISO 27001 Require It?
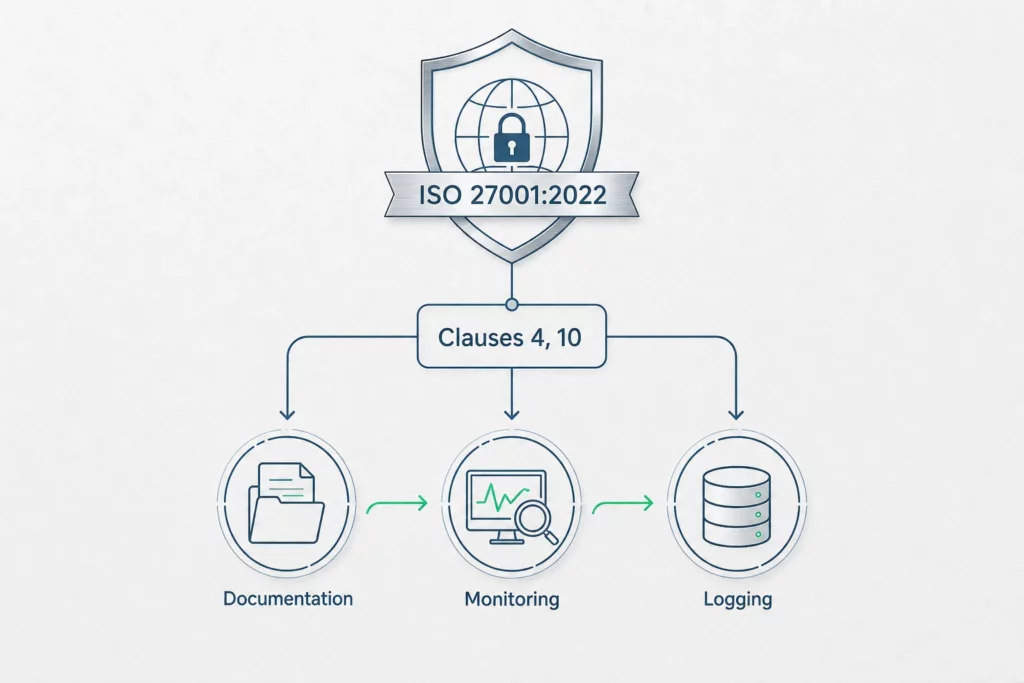
The answer is yes. ISO/IEC 27001:2022 mandates documentation across Clauses 4-10, with requirements that include continuous monitoring and logging of database activities. For any organization pursuing or maintaining ISO 27001 certification, database documentation is a mandated control, subject to audit – not a best practice left to individual team discretion.
Documentation as a compliance requirement
Beyond ISO 27001, documentation is a core requirement across SOC 2, GDPR, and HIPAA frameworks. Auditors ask which tables hold PII, who can access them, and how access is controlled. Organizations that cannot answer those questions quickly and accurately from their documentation fail audits – and incur remediation costs that dwarf the original investment in documentation infrastructure.
Security, access controls, and data governance alignment
Database documentation serves security by making the data landscape legible. When every sensitive field is labeled, every access path is recorded, and every table’s data classification is explicit, security teams can enforce controls with precision rather than guesswork. Data governance and database documentation share the same foundation: a complete, accurate record of what data exists, where it lives, and who is responsible for it.
Tools and Approaches: Are Spreadsheets Enough for Database Documentation?
For small, stable schemas, spreadsheets can capture documentation adequately. For any production database that receives schema updates – which describes the overwhelming share of real-world systems – spreadsheets and wikis fail on maintenance. They have no awareness of the database they describe, no change detection, no ERD generation, and no access controls aligned with the sensitivity of the data they document. A 200-table schema in a spreadsheet is unwieldy; a 1,000-table schema is unmanageable.
The automation advantage
The core limitation of manual tools is coupling, not speed. Timely Text (2026) notes that clear database documentation improves collaboration, onboarding, compliance, and troubleshooting across teams, while reducing delays and operational costs. Automation is what makes that clarity sustainable at scale: it removes the manual overhead, ensures structural consistency, and turns documentation from a discipline task into an automatic output of existing workflows.
Modern documentation platforms connect directly to live databases, generate ERDs automatically from schema imports, and store field-level metadata in formats accessible to engineers, analysts, and product managers alike. Key capabilities to evaluate: automatic ERD generation, field-level metadata management, native support for MySQL, PostgreSQL, and SQL Server in a single tool, and a local agent architecture that keeps raw database data within your own infrastructure rather than transmitting it externally.
Getting Started: Your Database Documentation Roadmap
Audit your current documentation state
Before adopting any process or platform, map what already exists. Which tables have descriptions? Which fields have business definitions? Where do ERDs live, and when were they last updated? An honest audit reveals the gap between documented intent and actual state – and identifies where documentation debt is most expensive to carry.
Prioritize high-value tables and relationships
Not all documentation carries equal weight. Start with the tables used in production-critical queries, the tables that hold PII or regulated data, and the tables at the center of the most frequent support requests. These are where documentation gaps cause the most operational damage – and where accurate documentation delivers the fastest return.
Choose a source-of-truth platform and collaborative workflow
Documentation lives and dies by adoption. A platform accessible only to engineers fails analysts and product managers. A platform where only the DBA can make updates creates a bottleneck. The right approach is a centralized source of truth accessible to all personas – with a freemium entry point that lets teams start immediately without a procurement cycle – backed by workflows that distribute documentation responsibility to the people closest to the data.
Frequently Asked Questions
What should database documentation include?
At minimum: schema and DDL scripts, a data dictionary with field-level business definitions, ERDs showing entity relationships and cardinality, documentation of SQL procedures and triggers, and user guides tailored to different audiences. Compliance-sensitive environments should also include data classification labels and access control records for each table holding regulated data.
Why is database documentation important for teams?
Documentation enables every team member to work with data independently – without relying on one person who holds the institutional knowledge. It reduces onboarding time, prevents errors caused by misunderstood field meanings, supports compliance reviews, and makes troubleshooting faster. Without it, knowledge is locked in individual memory and lost whenever people change roles or leave.
What are the main challenges in documenting databases manually?
Manual documentation breaks down on maintenance. A schema change requires a human to update the documentation – and if that step is skipped once, the documentation is inaccurate. Over time, it drifts from reality, teams stop trusting it, and the original investment is lost. Volume compounds the problem: a schema with hundreds of tables and thousands of columns is too large to document accurately by hand without dedicated tooling.
How often should database documentation be updated?
Every time the schema changes. Documentation updated quarterly or annually will be outdated within weeks in any active codebase. The practical solution is to tie documentation updates to deployment events – so that no schema migration ships without a corresponding documentation update.
What tools can help automate database documentation?
Platforms that connect directly to live databases – supporting MySQL, PostgreSQL, and SQL Server natively – and generate documentation automatically from schema imports are the most effective approach. Key capabilities to evaluate: automatic ERD generation, field-level metadata management, real-time collaboration across team personas, and a local agent architecture that keeps raw database data within your own infrastructure.
How does database documentation support compliance requirements?
ISO/IEC 27001:2022 explicitly mandates documented information management systems, including continuous monitoring and logging of database activities. SOC 2, GDPR, and HIPAA frameworks similarly require organizations to demonstrate control over their data – which depends on knowing what data they hold, where it lives, and who can access it. Accurate, current documentation is the foundation of that demonstration.